Model Information
Model Type
QWEN
Model Class
QWEN
Recommended Sampler
Default
Recommended Steps
30
Recommended CFG
1
CLIP Skip
1
Requests (24h)
11
Requests (7d)
119
Capabilities
Image to image, Inpainting, ControlNet, IP-Adapter
Added At
2/4/2026
Use Qwen-Image with the Arli AI API
Generate images with Qwen-Image through the OpenAI-style image endpoint. Send sd_model_checkpoint as the model name and the API renders the result without logging your prompts.
cURL
curl -X POST https://api.arliai.com/v1/txt2img \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer $ARLIAI_API_KEY" \
  -d '{
    "sd_model_checkpoint": "Qwen-Image",
    "prompt": "a red fox in fresh snow, cinematic light",
    "negative_prompt": "lowres, bad anatomy, watermark",
    "steps": 30,
    "sampler_name": "Default",
    "cfg_scale": 1,
    "width": 1024,
    "height": 1024
  }'
Python
import requests

response = requests.post(
    "https://api.arliai.com/v1/txt2img",
    headers={"Authorization": "Bearer YOUR_ARLIAI_API_KEY"},
    json={
        "sd_model_checkpoint": "Qwen-Image",
        "prompt": "a red fox in fresh snow, cinematic light",
        "steps": 30,
        "sampler_name": "Default",
        "cfg_scale": 1,
        "width": 1024,
        "height": 1024,
    },
)
print(response.json())
See the image generation docs for every parameter, or read the quick start guide to make your first request.
Similar image models
license: apache-2.0 language:
- en
- zh library_name: diffusers pipeline_tag: text-to-image

💜 Qwen Chat | 🤗 Hugging Face | 🤖 ModelScope | 📑 Tech Report | 📑 Blog
🖥️ Demo | 💬 WeChat (微信) | 🫨 Discord


Introduction
We are thrilled to release Qwen-Image, an image generation foundation model in the Qwen series that achieves significant advances in complex text rendering and precise image editing. Experiments show strong general capabilities in both image generation and editing, with exceptional performance in text rendering, especially for Chinese.

News
- 2025.08.04: We released the Technical Report of Qwen-Image!
- 2025.08.04: We released Qwen-Image weights! Check at huggingface and Modelscope!
- 2025.08.04: We released Qwen-Image! Check our blog for more details!
Quick Start
Install the latest version of diffusers
pip install git+https://github.com/huggingface/diffusers
The following contains a code snippet illustrating how to use the model to generate images based on text prompts:
from diffusers import DiffusionPipeline
import torch

model_name = "Qwen/Qwen-Image"

# Load the pipeline
if torch.cuda.is_available():
    torch_dtype = torch.bfloat16
    device = "cuda"
else:
    torch_dtype = torch.float32
    device = "cpu"

pipe = DiffusionPipeline.from_pretrained(model_name, torch_dtype=torch_dtype)
pipe = pipe.to(device)

positive_magic = {
    "en": ", Ultra HD, 4K, cinematic composition.", # for english prompt
    "zh": ", 超清,4K,电影级构图." # for chinese prompt
}

# Generate image
prompt = '''A coffee shop entrance features a chalkboard sign reading "Qwen Coffee 😊 $2 per cup," with a neon light beside it displaying "通义千问". Next to it hangs a poster showing a beautiful Chinese woman, and beneath the poster is written "π≈3.1415926-53589793-23846264-33832795-02384197". Ultra HD, 4K, cinematic composition'''

negative_prompt = " " # using an empty string if you do not have specific concept to remove


# Generate with different aspect ratios
aspect_ratios = {
    "1:1": (1328, 1328),
    "16:9": (1664, 928),
    "9:16": (928, 1664),
    "4:3": (1472, 1140),
    "3:4": (1140, 1472),
    "3:2": (1584, 1056),
    "2:3": (1056, 1584),
}

width, height = aspect_ratios["16:9"]

image = pipe(
    prompt=prompt + positive_magic["en"],
    negative_prompt=negative_prompt,
    width=width,
    height=height,
    num_inference_steps=50,
    true_cfg_scale=4.0,
    generator=torch.Generator(device="cuda").manual_seed(42)
).images[0]

image.save("example.png")
Show Cases
One of its standout capabilities is high-fidelity text rendering across diverse images. Whether it’s alphabetic languages like English or logographic scripts like Chinese, Qwen-Image preserves typographic details, layout coherence, and contextual harmony with stunning accuracy. Text isn’t just overlaid—it’s seamlessly integrated into the visual fabric.
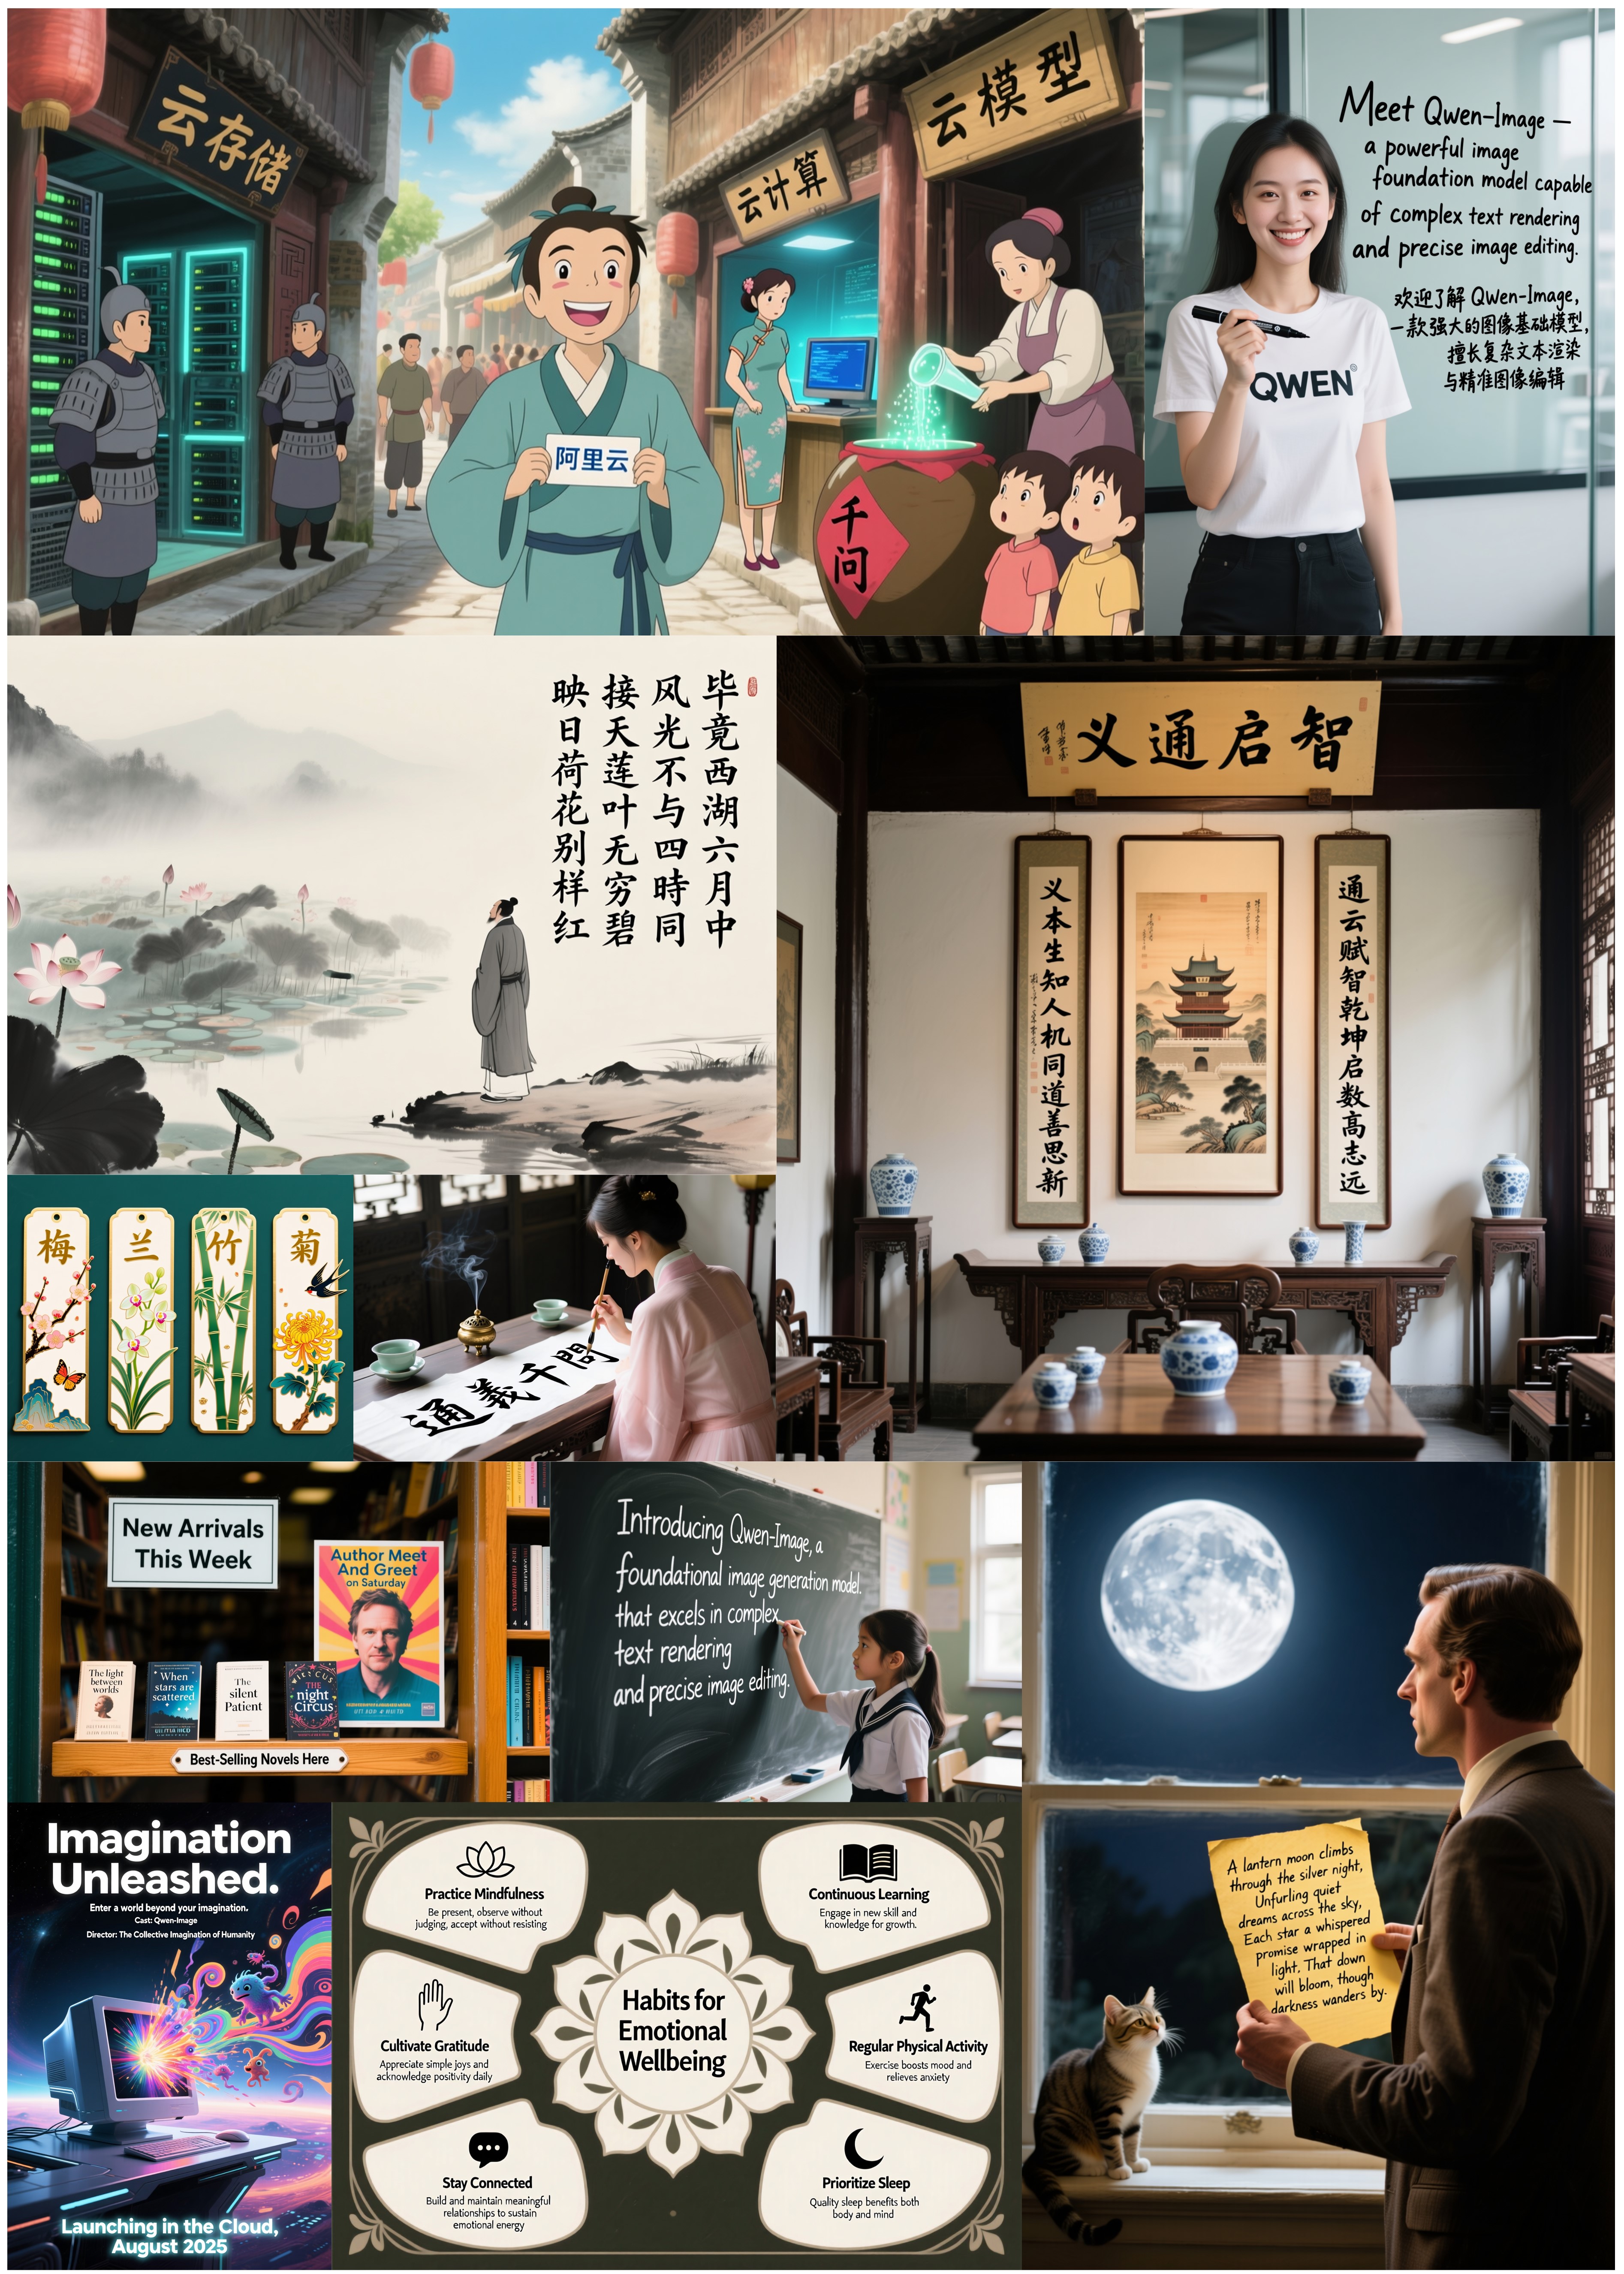
Beyond text, Qwen-Image excels at general image generation with support for a wide range of artistic styles. From photorealistic scenes to impressionist paintings, from anime aesthetics to minimalist design, the model adapts fluidly to creative prompts, making it a versatile tool for artists, designers, and storytellers.

When it comes to image editing, Qwen-Image goes far beyond simple adjustments. It enables advanced operations such as style transfer, object insertion or removal, detail enhancement, text editing within images, and even human pose manipulation—all with intuitive input and coherent output. This level of control brings professional-grade editing within reach of everyday users.

But Qwen-Image doesn’t just create or edit—it understands. It supports a suite of image understanding tasks, including object detection, semantic segmentation, depth and edge (Canny) estimation, novel view synthesis, and super-resolution. These capabilities, while technically distinct, can all be seen as specialized forms of intelligent image editing, powered by deep visual comprehension.

Together, these features make Qwen-Image not just a tool for generating pretty pictures, but a comprehensive foundation model for intelligent visual creation and manipulation—where language, layout, and imagery converge.
License Agreement
Qwen-Image is licensed under Apache 2.0.
Citation
We kindly encourage citation of our work if you find it useful.
@misc{wu2025qwenimagetechnicalreport,
      title={Qwen-Image Technical Report},
      author={Chenfei Wu and Jiahao Li and Jingren Zhou and Junyang Lin and Kaiyuan Gao and Kun Yan and Sheng-ming Yin and Shuai Bai and Xiao Xu and Yilei Chen and Yuxiang Chen and Zecheng Tang and Zekai Zhang and Zhengyi Wang and An Yang and Bowen Yu and Chen Cheng and Dayiheng Liu and Deqing Li and Hang Zhang and Hao Meng and Hu Wei and Jingyuan Ni and Kai Chen and Kuan Cao and Liang Peng and Lin Qu and Minggang Wu and Peng Wang and Shuting Yu and Tingkun Wen and Wensen Feng and Xiaoxiao Xu and Yi Wang and Yichang Zhang and Yongqiang Zhu and Yujia Wu and Yuxuan Cai and Zenan Liu},
      year={2025},
      eprint={2508.02324},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2508.02324},
}