GLM-4.6-Derestricted-v5
Derestricted
GLM-4.6-Derestricted-v5 is a text generation model available on Arli AI. It offers 355B parameters, 203K token context, reasoning support. Recommended use: Derestricted. Run it through the OpenAI-compatible chat completions API with unlimited requests and zero-log privacy.
View on Hugging FaceBack to ModelsHourly Usage
Token Usage
Input (24H)
75M
Output (24H)
700K
Input (7D)
536M
Output (7D)
5M
Performance Metrics
Typical Total Time
15.14s
Typical TTFT
2.01s
Typical Input TPS
2421.99
Typical Output TPS
27.04
Model Information
Context Size
202752
Quantization
INT8-INT4 Mixed
Engine
vllm
Creation Method
Surgical
Model Class
GLM-4.6-Derestricted
Chat Template
GLM4
Reasoning
Yes
Vision
No
Parameters
355B
Added At
12/6/2025
Use GLM-4.6-Derestricted-v5 with the Arli AI API
GLM-4.6-Derestricted-v5 is available through an OpenAI-compatible chat completions endpoint. Point any OpenAI SDK at https://api.arliai.com/v1, pass GLM-4.6-Derestricted-v5 as the model, and requests are served without logging.
cURL
curl https://api.arliai.com/v1/chat/completions \
  -H "Authorization: Bearer $ARLIAI_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "GLM-4.6-Derestricted-v5",
    "messages": [{"role": "user", "content": "Hello!"}]
  }'
Python
from openai import OpenAI

client = OpenAI(
    base_url="https://api.arliai.com/v1",
    api_key="YOUR_ARLIAI_API_KEY",
)

response = client.chat.completions.create(
    model="GLM-4.6-Derestricted-v5",
    messages=[{"role": "user", "content": "Hello!"}],
)
print(response.choices[0].message.content)
See the text generation docs for every parameter, or read the quick start guide to make your first request.
license: mit thumbnail: >- https://cdn-uploads.huggingface.co/production/uploads/6625f4a8a8d1362ebcc3851a/iyzgR89q50pp1T8HeeP15.png base_model:
- zai-org/GLM-4.6 pipeline_tag: text-generation tags:
- abliterated
- derestricted
- glm-4.6
- unlimited
- uncensored library_name: transformers

Arli AI
GLM-4.6-Derestricted

GLM-4.6-Derestricted is a Derestricted version of GLM-4.6, created by Arli AI.
Our goal with this release is to provide a version of the model that removed refusal behaviors while maintaining the high-performance reasoning of the original GLM-4.6. This is unlike regular abliteration which often inadvertently "lobotomizes" the model.
Methodology: Norm-Preserving Biprojected Abliteration
To achieve this, Arli AI utilized Norm-Preserving Biprojected Abliteration, a refined technique pioneered by Jim Lai (grimjim). You can read the full technical breakdown in this article.
Why this matters:
Standard abliteration works by simply subtracting a "refusal vector" from the model's weights. While this works to uncensor a model, it is mathematically unprincipled. It alters the magnitude (or "loudness") of the neurons, destroying the delicate feature norms the model learned during training. This damage is why many uncensored models suffer from degraded logic or hallucinations.
How Norm-Preserving Biprojected Abliteration fixes it:
This model was modified using a three-step approach that removes refusals without breaking the model's brain:
- Biprojection (Targeting): We refined the refusal direction to ensure it is mathematically orthogonal to "harmless" directions. This ensures that when we cut out the refusal behavior, we do not accidentally cut out healthy, harmless concepts.
- Decomposition: Instead of a raw subtraction, we decomposed the model weights into Magnitude and Direction.
- Norm-Preservation: We removed the refusal component solely from the directional aspect of the weights, then recombined them with their original magnitudes.
The Result:
By preserving the weight norms, we maintain the "importance" structure of the neural network. Benchmarks suggest that this method avoids the "Safety Tax"—not only effectively removing refusals but potentially improving reasoning capabilities over the baseline, as the model is no longer wasting compute resources on suppressing its own outputs.
In fact, you may find surprising new knowledge and capabilities that the original model does not initially expose.
Quantization:
- Original: https://huggingface.co/ArliAI/GLM-4.6-Derestricted
- FP8: https://huggingface.co/ArliAI/GLM-4.6-Derestricted-FP8
- INT8: https://huggingface.co/ArliAI/GLM-4.6-Derestricted-W8A8-INT8
- W4A16: https://huggingface.co/ArliAI/GLM-4.6-Derestricted-GPTQ-W4A16
Original model card:
-# GLM-4.6

👋 Join our Discord community.
📖 Check out the GLM-4.6 technical blog, technical report(GLM-4.5), and Zhipu AI technical documentation.
📍 Use GLM-4.6 API services on Z.ai API Platform.
👉 One click to GLM-4.6.
Model Introduction
Compared with GLM-4.5, GLM-4.6 brings several key improvements:
- Longer context window: The context window has been expanded from 128K to 200K tokens, enabling the model to handle more complex agentic tasks.
- Superior coding performance: The model achieves higher scores on code benchmarks and demonstrates better real-world performance in applications such as Claude Code、Cline、Roo Code and Kilo Code, including improvements in generating visually polished front-end pages.
- Advanced reasoning: GLM-4.6 shows a clear improvement in reasoning performance and supports tool use during inference, leading to stronger overall capability.
- More capable agents: GLM-4.6 exhibits stronger performance in tool using and search-based agents, and integrates more effectively within agent frameworks.
- Refined writing: Better aligns with human preferences in style and readability, and performs more naturally in role-playing scenarios.
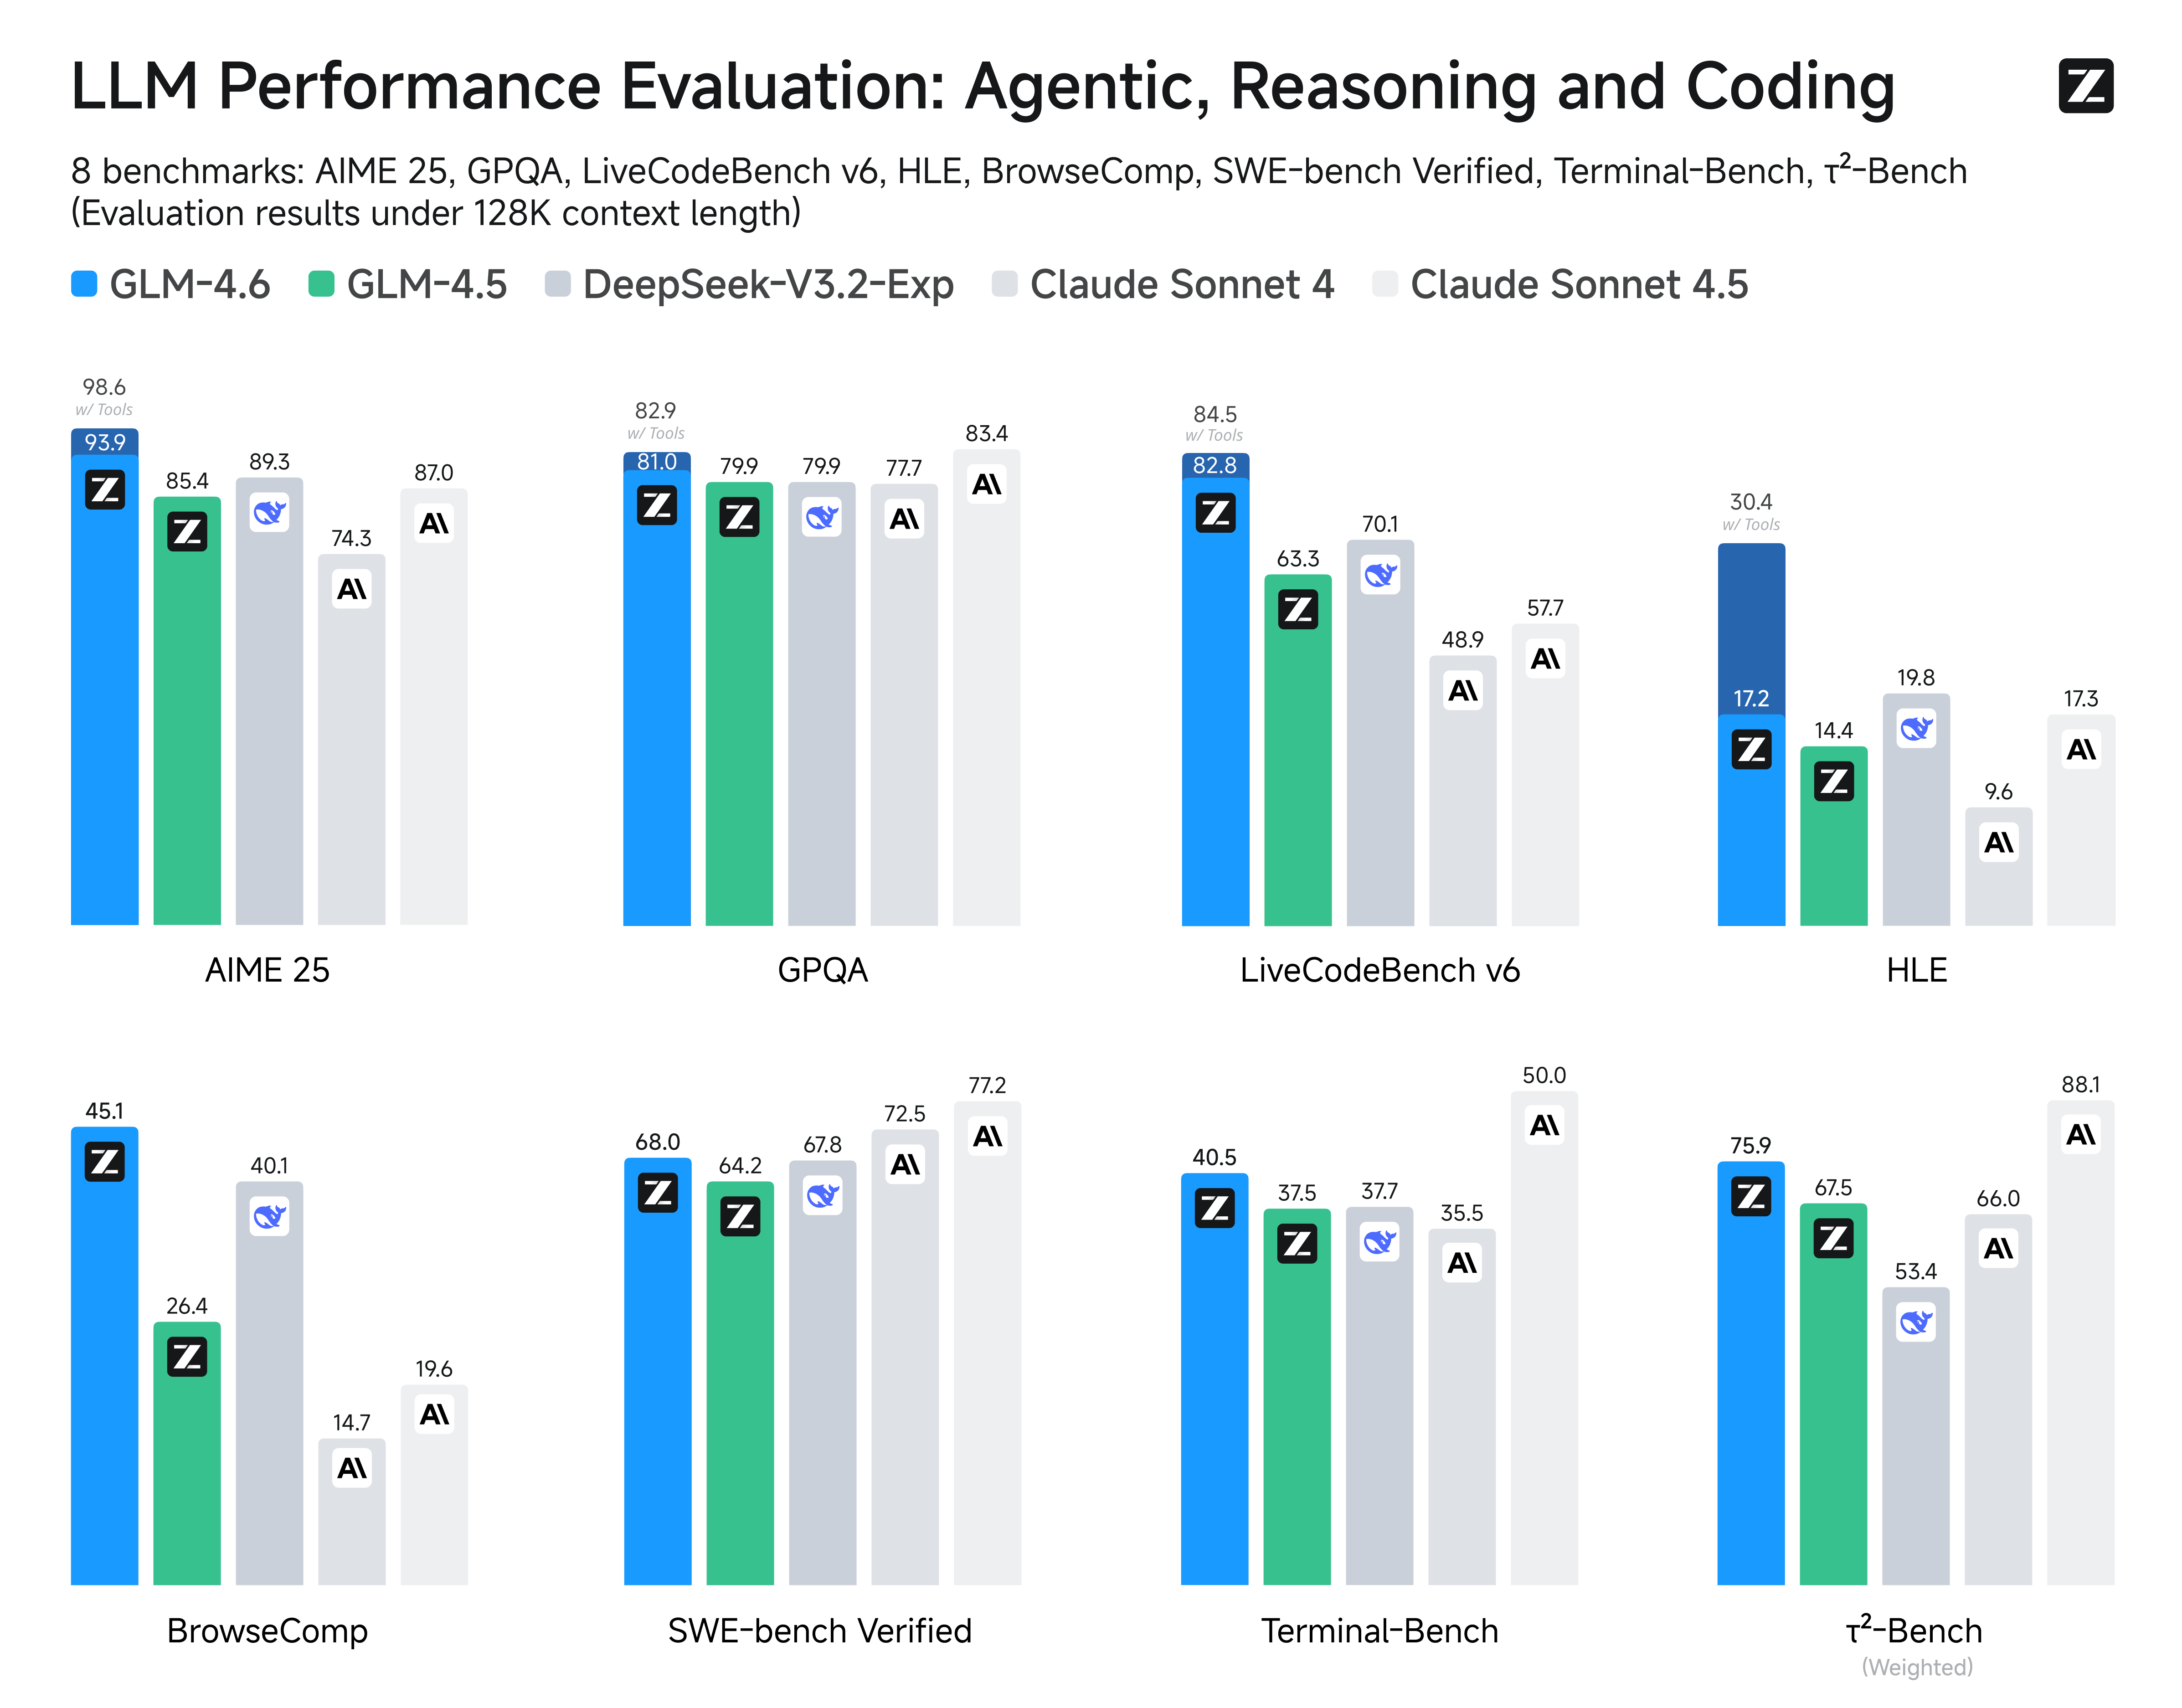
We evaluated GLM-4.6 across eight public benchmarks covering agents, reasoning, and coding. Results show clear gains over GLM-4.5, with GLM-4.6 also holding competitive advantages over leading domestic and international models such as DeepSeek-V3.1-Terminus and Claude Sonnet 4.
Inference
Both GLM-4.5 and GLM-4.6 use the same inference method.
you can check our github for more detail.
Recommended Evaluation Parameters
For general evaluations, we recommend using a sampling temperature of 1.0.
For code-related evaluation tasks (such as LCB), it is further recommended to set:
top_p = 0.95top_k = 40