
Hourly Usage
Performance Metrics
Typical Total Time
42.15s
Typical TTFT
22.41s
Typical Prefill TPS
370.64
Typical Gen TPS
10.72
Model Information
Context Size
262144
Quantization
r128 on INT8
Engine
vllm
Creation Method
Surgical
Model Type
Gemma31B
Chat Template
Gemma4
Reasoning
Yes
Vision
Yes
Parameters
31B
Added At
10/16/2026
license: mit thumbnail: >- https://cdn-uploads.huggingface.co/production/uploads/6625f4a8a8d1362ebcc3851a/iyzgR89q50pp1T8HeeP15.png base_model:
- zai-org/GLM-4.6 pipeline_tag: text-generation tags:
- abliterated
- derestricted
- glm-4.6
- unlimited
- uncensored library_name: transformers

Arli AI
GLM-4.6-Derestricted

GLM-4.6-Derestricted is a Derestricted version of GLM-4.6, created by Arli AI.
Our goal with this release is to provide a version of the model that removed refusal behaviors while maintaining the high-performance reasoning of the original GLM-4.6. This is unlike regular abliteration which often inadvertently "lobotomizes" the model.
Methodology: Norm-Preserving Biprojected Abliteration
To achieve this, Arli AI utilized Norm-Preserving Biprojected Abliteration, a refined technique pioneered by Jim Lai (grimjim). You can read the full technical breakdown in this article.
Why this matters:
Standard abliteration works by simply subtracting a "refusal vector" from the model's weights. While this works to uncensor a model, it is mathematically unprincipled. It alters the magnitude (or "loudness") of the neurons, destroying the delicate feature norms the model learned during training. This damage is why many uncensored models suffer from degraded logic or hallucinations.
How Norm-Preserving Biprojected Abliteration fixes it:
This model was modified using a three-step approach that removes refusals without breaking the model's brain:
- Biprojection (Targeting): We refined the refusal direction to ensure it is mathematically orthogonal to "harmless" directions. This ensures that when we cut out the refusal behavior, we do not accidentally cut out healthy, harmless concepts.
- Decomposition: Instead of a raw subtraction, we decomposed the model weights into Magnitude and Direction.
- Norm-Preservation: We removed the refusal component solely from the directional aspect of the weights, then recombined them with their original magnitudes.
The Result:
By preserving the weight norms, we maintain the "importance" structure of the neural network. Benchmarks suggest that this method avoids the "Safety Tax"—not only effectively removing refusals but potentially improving reasoning capabilities over the baseline, as the model is no longer wasting compute resources on suppressing its own outputs.
In fact, you may find surprising new knowledge and capabilities that the original model does not initially expose.
Quantization:
- Original: https://huggingface.co/ArliAI/GLM-4.6-Derestricted
- FP8: https://huggingface.co/ArliAI/GLM-4.6-Derestricted-FP8
- INT8: https://huggingface.co/ArliAI/GLM-4.6-Derestricted-W8A8-INT8
- W4A16: https://huggingface.co/ArliAI/GLM-4.6-Derestricted-GPTQ-W4A16
Original model card:
-# GLM-4.6

👋 Join our Discord community.
📖 Check out the GLM-4.6 technical blog, technical report(GLM-4.5), and Zhipu AI technical documentation.
📍 Use GLM-4.6 API services on Z.ai API Platform.
👉 One click to GLM-4.6.
Model Introduction
Compared with GLM-4.5, GLM-4.6 brings several key improvements:
- Longer context window: The context window has been expanded from 128K to 200K tokens, enabling the model to handle more complex agentic tasks.
- Superior coding performance: The model achieves higher scores on code benchmarks and demonstrates better real-world performance in applications such as Claude Code、Cline、Roo Code and Kilo Code, including improvements in generating visually polished front-end pages.
- Advanced reasoning: GLM-4.6 shows a clear improvement in reasoning performance and supports tool use during inference, leading to stronger overall capability.
- More capable agents: GLM-4.6 exhibits stronger performance in tool using and search-based agents, and integrates more effectively within agent frameworks.
- Refined writing: Better aligns with human preferences in style and readability, and performs more naturally in role-playing scenarios.
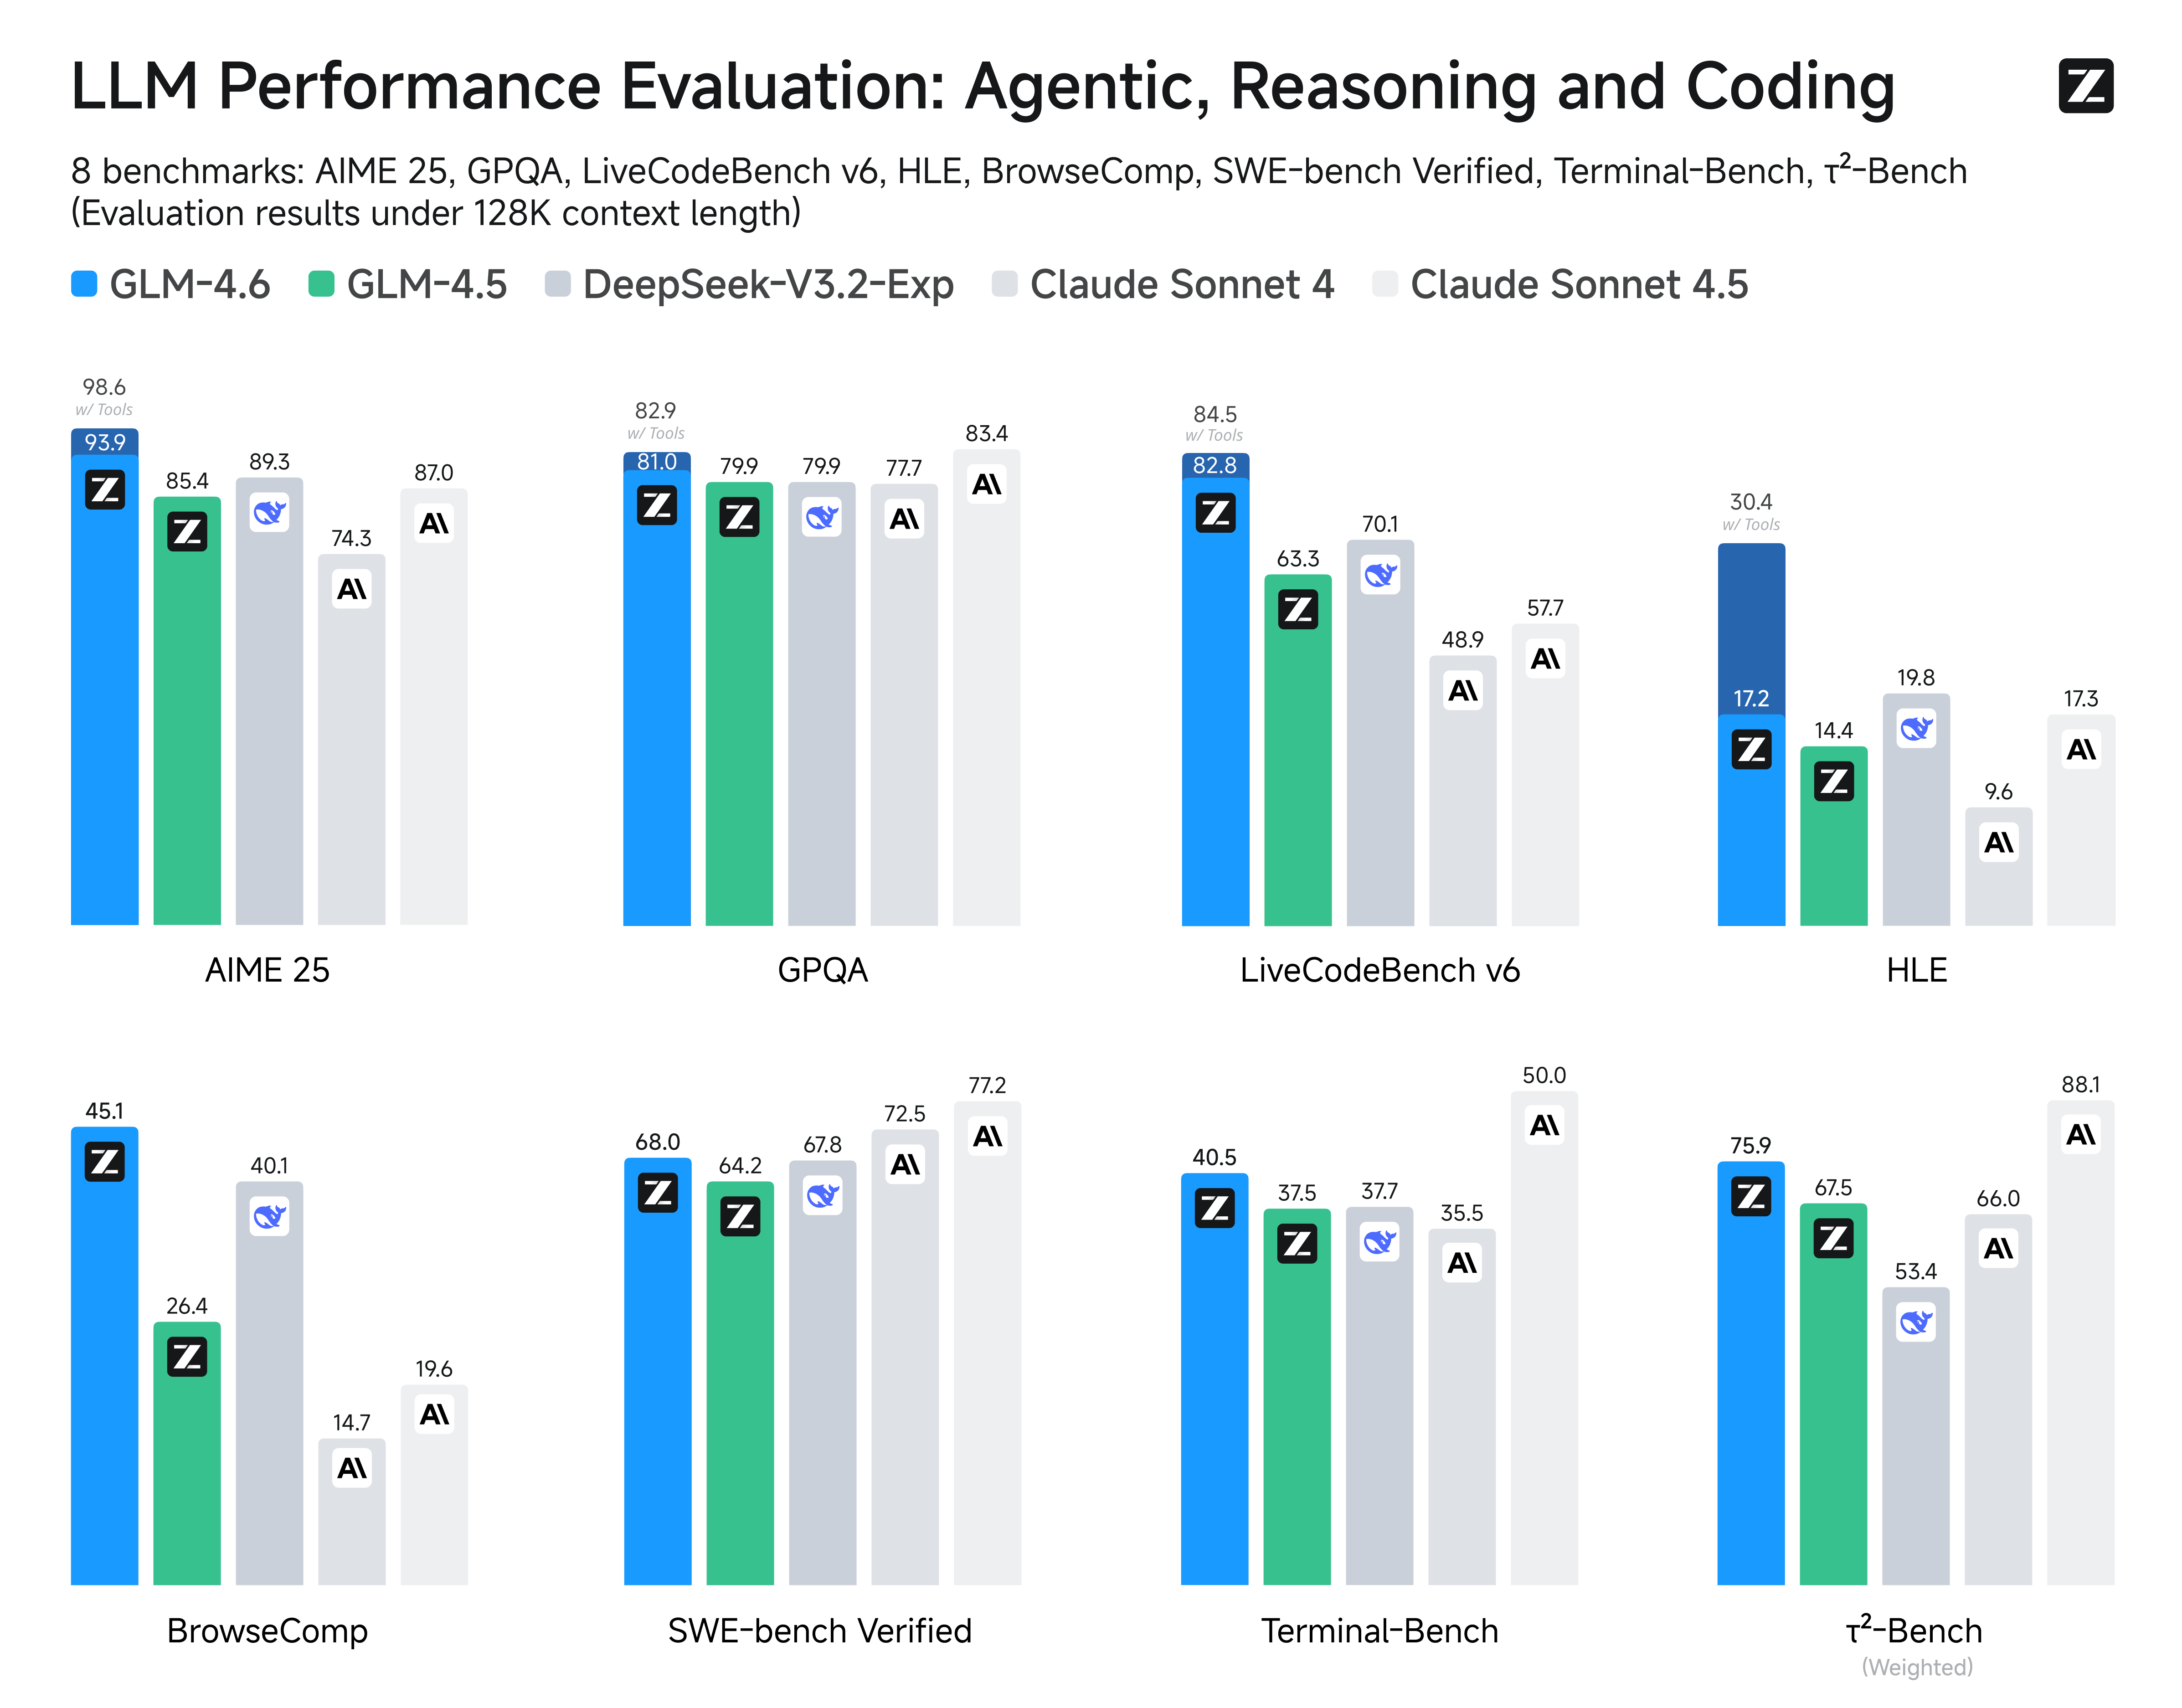
We evaluated GLM-4.6 across eight public benchmarks covering agents, reasoning, and coding. Results show clear gains over GLM-4.5, with GLM-4.6 also holding competitive advantages over leading domestic and international models such as DeepSeek-V3.1-Terminus and Claude Sonnet 4.
Inference
Both GLM-4.5 and GLM-4.6 use the same inference method.
you can check our github for more detail.
Recommended Evaluation Parameters
For general evaluations, we recommend using a sampling temperature of 1.0.
For code-related evaluation tasks (such as LCB), it is further recommended to set:
top_p = 0.95top_k = 40